Web Crawler vs Web Scraper: The Differences
Executive Summary
In 2025, as AI and big data fuel business innovation, understanding data crawling versus targeted extraction is essential for developers, marketers, and analysts. This guide breaks down the dynamics of crawlers vs. scrapers, highlighting how crawling and scraping work together to build efficient data pipelines.
Key insights include:
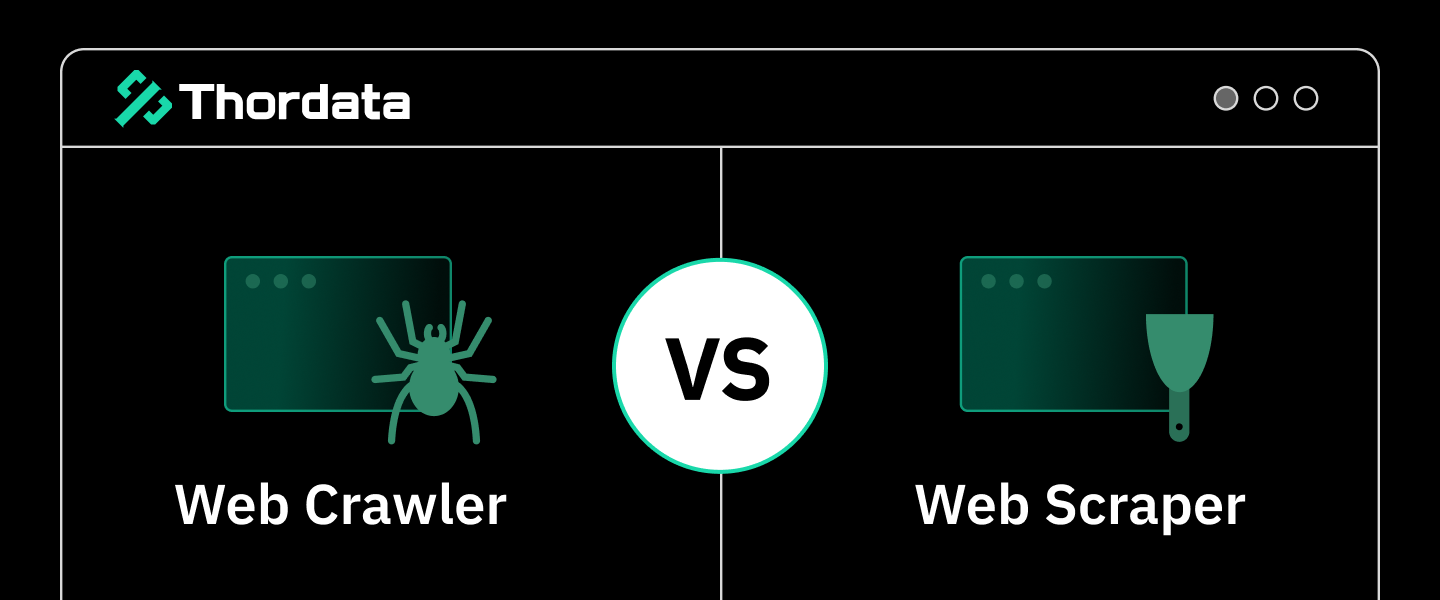
● Crawler vs Scraper: Crawlers systematically explore websites to index links, while scrapers pull specific data like prices or reviews from those pages.
● Data Crawling Essentials: Automate discovery of vast web resources without overwhelming servers, using bots for scalable indexing.
● Crawl and Scrape Synergy: Combine both for end-to-end workflows, from URL harvesting to actionable insights in e-commerce or SEO.
● 2025 Trends: With privacy regs like GDPR 2.0, ethical crawling and scraping prioritize consent and rate-limiting for sustainable operations.
● Tools Spotlight: Open-source options like Scrapy for crawling and BeautifulSoup for scraping, tested for modern JavaScript-heavy sites.
Whether optimizing SEO strategies or monitoring competitors, mastering these tools boosts data-driven decisions without legal pitfalls.
A quick answer
Web crawling gathers pages to create indices or collections. On the other hand, web scraping downloads pages to extract a specific set of data for analysis purposes, for example, product details, pricing information, SEO data, or any other data sets.
Both scraping and crawling go hand in hand in the whole data-gathering process, so usually, when one is done, the other follows. For instance, once you discover URLs through web crawling, you can visit them with a web scraper to download the HTML and extract the data you need.
What Is Web Crawling?
Web crawling forms the backbone of data crawling, where automated bots—known as crawlers—traverse the internet like digital explorers, following hyperlinks to map out site structures. Unlike manual browsing, a crawler starts from seed URLs (e.g., a homepage) and recursively visits linked pages, queuing new discoveries while respecting robots.txt directives.
In practice, data crawling indexes content for search engines or custom datasets, handling petabytes of web data daily. Google’s crawler, for instance, processes over 100 billion pages monthly, demonstrating scale. For businesses, this means building comprehensive archives for trend analysis or content auditing.
Core Mechanics of a Web Crawler
At its heart, a crawler employs a frontier queue: It fetches a page, parses HTML for outbound links, and adds unvisited ones to the queue. Politeness policies—delaying requests to avoid server overload—ensure ethical operation. Tools like Apache Nutch excel here, integrating with Hadoop for distributed data crawling in cloud environments.
A crawler program simply goes online to look for two things:
1. The data the user is searching for
2. More targets to crawl
So if we tried to crawl a real web page, the process would look something like this:
1. The crawler goes to your predefined target – http://example.com
2. Discovers product pages
3. Then finds the product data (price, title, description, etc.)
What Is Web Scraping?
Web scraping zooms in where crawling casts a wide net, focusing on crawling and scraping as a targeted duo. A scraper downloads a page’s raw HTML (or API response) and applies parsing logic to extract nuggets like product specs, user sentiments, or stock prices—transforming unstructured web chaos into structured CSV or JSON gold.
This process thrives in niches like lead generation, where scraping LinkedIn profiles yields contact details without full-site traversal. In 2025, with SPAs dominating (e.g., React apps), headless browsers like Puppeteer enable JavaScript rendering, making scrapers indispensable for dynamic content.
Parsing Techniques for Effective Scraping
Scrapers leverage libraries such as lxml for XPath queries or regex for pattern matching. For robustness, incorporate error handling: If a site’s layout shifts, fallback selectors prevent pipeline breaks. Real-world example: Extracting Amazon review scores via CSS selectors like .a-icon-alt for sentiment analysis.
Key Differences: Crawler vs Scraper in Action
The crawler vs scraper debate boils down to scope and intent—crawlers discover, scrapers deliver. Crawlers mimic a library cataloger, amassing links for later use; scrapers act as librarians, pulling exact quotes from books. In data crawling, the former handles breadth (millions of URLs), the latter depth (granular fields per page).
Quantitatively: A crawler might index 10,000 pages/hour on a mid-tier server, while a scraper processes 1,000 extractions/minute with 99% accuracy. Overlap occurs in hybrid tools, but misapplying them wastes resources—using a scraper for link discovery is inefficient, just as crawling without extraction yields raw, unusable dumps.
Comparative Table: At a Glance
|
Aspect |
Web Crawler (Data Crawling Focus) |
Web Scraper (Extraction Focus) |
|
Primary Goal |
Link discovery and site mapping |
Specific data harvesting (e.g., prices, emails) |
|
Scale |
Large (site-wide or internet-scale) |
Targeted (single pages or patterns) |
|
Automation |
Requires bots for recursion |
Can be manual for one-offs; bots for volume |
|
Output |
Indexed URLs or sitemaps |
Structured datasets (JSON, databases) |
|
Challenges |
Duplicate handling, crawl budget management |
Anti-bot evasion, schema changes |
This table underscores why crawling and scraping pair perfectly: Crawl first, scrape selectively.
When to Use Crawling and Scraping: Real-World Use Cases
Choose data crawling for exploratory tasks like SEO audits—crawl a domain to identify broken links or thin content, informing crawl budget optimization. Conversely, deploy scraping for competitive intel: Monitor rival pricing on 50 e-tailers weekly, automating alerts for drops below 10%.
In lead gen, combine them: Crawl directories for firm URLs, then scrape bios for C-suite emails. For sentiment tracking, crawl social feeds via APIs, scraping comments for NLP-ready text. 2025’s edge: AI-augmented pipelines, where crawlers feed LLMs for semantic filtering before scraping.
According to Mckinsey Global Institute, data-driven organizations are 23 times more likely to acquire customers. They are also six times more likely to retain customers and 19 times more likely to be profitable. Leveraging this data enables enterprises to make more informed decisions and improve customer experience.
Industry Spotlights: E-Commerce and SEO
E-commerce giants like Shopify use crawlers to baseline inventory graphs, scraping for real-time stock APIs. SEO pros crawl backlink profiles with Ahrefs, scraping meta tags to refine keyword strategies—boosting organic traffic by 25% per recent BrightEdge reports.
PR, brand, and risk management
With data scraping, you’ll be able to detect ad fraud, improve ad performance, and check advertisers’ landing pages, as well as monitor your brand mentions and take appropriate actions for brand protection.
Tools and Technologies: Building Your Crawler vs Scraper Arsenal
Empower crawler vs scraper workflows with open-source staples. For crawling, Scrapy (Python-based) offers built-in politeness and middleware for proxies, scaling to 1M pages/day. Pair it with Scrapy-Splash for JS sites.
Scraping shines with BeautifulSoup for lightweight parsing or Selenium for browser automation. Cloud options like Bright Data provide managed proxies, dodging CAPTCHA in data crawling. Integration tip: Use Airflow to orchestrate—crawl daily, scrape on triggers.
Emerging 2025 Tools: AI-Infused Options
LangChain’s web loaders now incorporate LLM-driven selectors, auto-adapting to layout drifts. For ethical compliance, Crawl4AI embeds consent checks, aligning with evolving CCPA rules.
Challenges and Best Practices for Ethical Data Crawling
Crawling and scraping invite hurdles: Rate limits cause 429 errors; IP bans halt jobs. Mitigate with rotating proxies and user-agent randomization. Legally, honor robots.txt and ToS—scraping public data is fair game, but private forums risk lawsuits.
Best practices: Implement deduplication via Bloom filters in crawlers; validate scraped data against schemas. Monitor ethics: Anonymize PII during extraction. In 2025, blockchain-verified crawls emerge for audit trails, ensuring transparency.
Conclusion
Navigating crawler vs scraper nuances unlocks powerful data crawling strategies, blending exploration with precision for 2025’s data-hungry landscape. By aligning tools to tasks—crawling for maps, scraping for mines—you’ll craft resilient pipelines that drive revenue and insights. Start small: Prototype a hybrid script today, scaling ethically to outpace competitors in an AI-accelerated world.
We hope the information provided is helpful. However, if you have any further questions, feel free to contact us at support@thordata.com or via online chat.

Frequently asked questions
What is the main difference between a web crawler and web scraper?
A web crawler systematically discovers and indexes URLs across sites (data crawling), while a web scraper extracts specific elements like text or images from known pages—ideal for crawling and scraping combos.
When should I use crawling vs scraping for data collection?
Opt for crawling to map large sites or discover content; use scraping for targeted pulls like prices. Integrate both in crawler vs scraper workflows for comprehensive data crawling.
Is web scraping legal in 2025?
Yes, for public data if you respect robots.txt and ToS—focus on ethical crawling and scraping to avoid blocks, prioritizing proxies and rate limits.
About the author
Jenny is a Content Specialist with a deep passion for digital technology and its impact on business growth. She has an eye for detail and a knack for creatively crafting insightful, results-focused content that educates and inspires. Her expertise lies in helping businesses and individuals navigate the ever-changing digital landscape.
The thordata Blog offers all its content in its original form and solely for informational intent. We do not offer any guarantees regarding the information found on the thordata Blog or any external sites that it may direct you to. It is essential that you seek legal counsel and thoroughly examine the specific terms of service of any website before engaging in any scraping endeavors, or obtain a scraping permit if required.

 Looking for
Top-Tier Residential Proxies?