Web Scraper API Guide: Python, Node.js and cURL
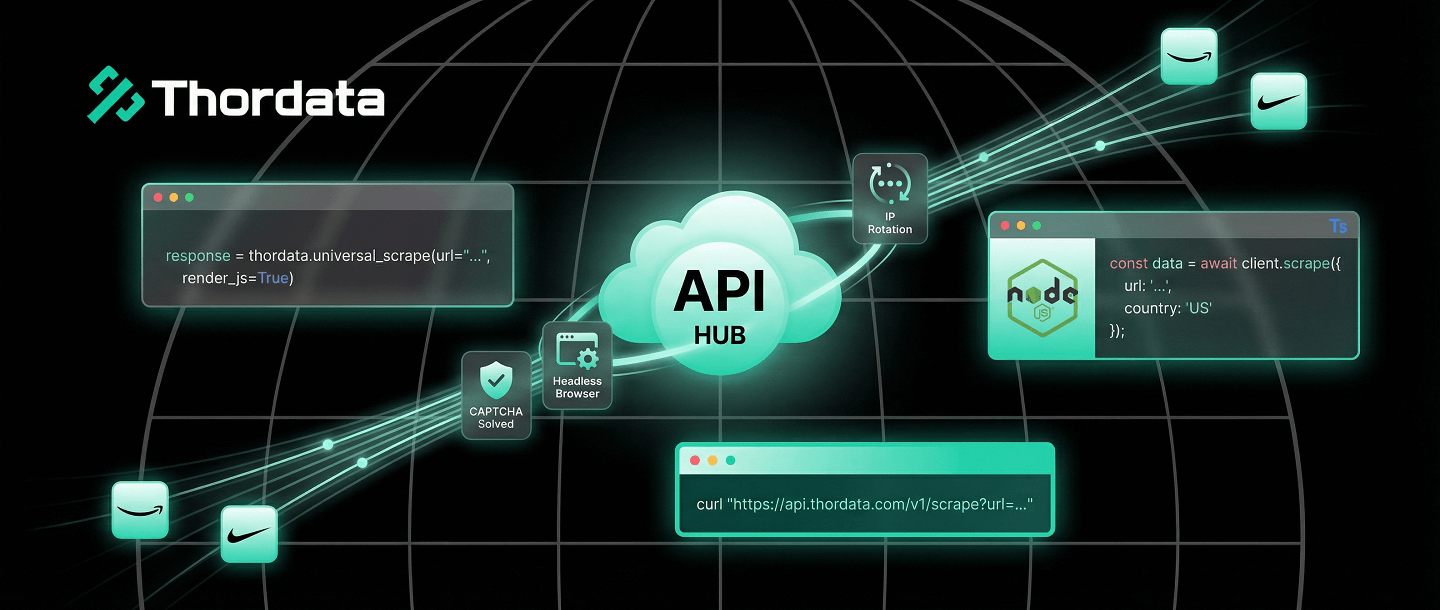
- The “Unblockable” Advantage: APIs like Thordata Web Scraper API handle CAPTCHAs, TLS fingerprinting, and IP rotation automatically.
- SDK vs. Manual Requests: While cURL is great for testing, the official Thordata Python/Node.js SDKs provide type safety, automatic retries, and cleaner code for production.
- Build vs. Buy: Switching to an API reduces maintenance time by ~80%, allowing teams to focus on data analysis rather than infrastructure repair.
There are two ways to scrape the web. The hard way involves managing thousands of proxies, rotating User-Agents, solving CAPTCHAs, and patching your Puppeteer script every time Chrome updates.
The smart way is to offload that entire stack to a Web Scraper API. You send a URL; you get back clean HTML or JSON. No blocks. No headaches.
In this guide, I will show you how to integrate Thordata’s API into your workflow using standard cURL requests, and more importantly, using our robust Python and Node.js SDKs.
1. The Concept: Your Proxy on Steroids
A standard proxy just changes your IP address. A Scraper API acts as a complete browser in the cloud.
- Request: You call
api.thordata.comwith your target URL. - Processing: We spin up a headless browser, route traffic through a residential IP, solve any challenges (Cloudflare Turnstile, etc.), and render the JavaScript.
- Response: We return the final HTML source code to you.
2. Quick Start: cURL (The Universal Language)
The fastest way to test an API is via the terminal. This verifies your API token and the connectivity.
curl "https://api.thordata.com/v1/scraper?token=YOUR_API_TOKEN&url=https://www.amazon.com&render_js=true"3. The Modern Way: Thordata Python SDK
Using raw `requests` is fine, but the official SDK handles error parsing, type hints, and retries for you. This is the preferred method for enterprise Python projects.
pip install thordata-sdkfrom thordata import ThordataClient
# Initialize with your token
client = ThordataClient(scraper_token="YOUR_TOKEN")
print("🚀 Scraping dynamic content...")
# universal_scrape handles JS rendering automatically
html = client.universal_scrape(
url="https://www.nike.com/launch",
js_render=True,
wait_for=".product-card", # Wait for specific element
country="us"
)
print(f"Success! Retrieved {len(html)} bytes.")
# You can now parse 'html' with BeautifulSoup4. The Node.js SDK (TypeScript Ready)
For JavaScript/TypeScript developers, our NPM package provides full type support.
npm install thordata-sdkimport { ThordataClient } from "thordata-sdk";
const client = new ThordataClient({
scraperToken: "YOUR_TOKEN"
});
async function run() {
const html = await client.universalScrape({
url: "https://www.walmart.com",
jsRender: true,
outputFormat: "html"
});
console.log("Data fetched:", html.substring(0, 200));
}
run();5. The Economic Argument: Build vs. Buy
Why pay for an API when you can write a scraper for free? Because “free” scrapers are expensive to maintain.
| Component | DIY (Do It Yourself) | Thordata API |
|---|---|---|
| IP Rotation | Buy proxy pools ($500+/mo), manage rotation logic. | Included automatically. |
| Headless Browser | Manage Puppeteer clusters, high RAM costs. | Included (Cloud Rendering). |
| Anti-Bot Evasion | Constantly patching fingerprinting leaks. | Handled by Thordata engineers. |
| Success Rate | Variable (breaks often). | 99.9% guaranteed. |
Conclusion
The Web Scraper API allows you to focus on what matters: the data. By abstracting away the complexity of proxies and headless browsers, you turn web scraping into a simple function call. Start with the SDKs today to build resilient pipelines in minutes, not days.

Frequently asked questions
Why use a Web Scraper API instead of local proxies?
Local proxies only rotate IPs. An API handles IP rotation, header management (User-Agents), CAPTCHA solving, and JavaScript rendering (Headless Browser) in a single request, saving you hundreds of engineering hours.
How does the Python SDK simplify scraping?
The Thordata Python SDK abstracts away HTTP request complexity. The ‘universal_scrape’ method automatically handles JS rendering parameters and retries, returning clean HTML or JSON with a single function call.
What is the cost difference?
Building a robust scraper requires developer salaries, server costs, and proxy subscriptions. An API model charges only for successful requests, often reducing Total Cost of Ownership (TCO) by 60-70% for small to medium teams.
About the author
Kael is a Senior Technical Copywriter at Thordata. He works closely with data engineers to document best practices for bypassing anti-bot protections. He specializes in explaining complex infrastructure concepts like residential proxies and TLS fingerprinting to developer audiences. All code examples in this article have been tested in real-world scraping scenarios.
The thordata Blog offers all its content in its original form and solely for informational intent. We do not offer any guarantees regarding the information found on the thordata Blog or any external sites that it may direct you to. It is essential that you seek legal counsel and thoroughly examine the specific terms of service of any website before engaging in any scraping endeavors, or obtain a scraping permit if required.

 Looking for
Top-Tier Residential Proxies?